OpenRouter ਪ੍ਰੋਵਾਈਡਰ ਰਾਊਟਿੰਗ: ਮਾਡਲ ਗੁਣਵੱਤਾ, ਟੋਕਨ ਸੀਮਾਵਾਂ ਅਤੇ ਅਸਲ ਲਾਗਤਾਂ
Table of Contents
OpenRouter ਪ੍ਰੋਵਾਈਡਰ ਰਾਊਟਿੰਗ ਇਹ ਤੈਅ ਕਰਦੀ ਹੈ ਕਿ ਤੁਹਾਡੀ request ਦਾ ਜਵਾਬ ਕਿਹੜੀ inference service ਦੇਵੇਗੀ। ਇੱਕੋ model name ਵਾਲੀਆਂ ਦੋ calls ਵੀ endpoint limits, supported parameters, serving software ਅਤੇ routing preferences ਉੱਤੇ ਨਿਰਭਰ ਕਰਦੀਆਂ ਹਨ। ਜਦੋਂ ਜਵਾਬ ਛੋਟੇ ਹੋ ਜਾਣ ਜਾਂ tool calls fail ਹੋਣ, quantization ਨੂੰ ਦੋਸ਼ ਦੇਣ ਤੋਂ ਪਹਿਲਾਂ ਇਹ ਫਰਕ ਜਾਂਚੋ।
ਮੁੱਖ ਗੱਲਾਂ
- Precision labels numerical format ਦੱਸਦੇ ਹਨ, accuracy score ਨਹੀਂ।
- Endpoint limits context, output length ਅਤੇ feature support ਤੈਅ ਕਰਦੇ ਹਨ।
- Explicit routing ਨੂੰ provider preference ਦੇ ਨਾਲ fallback policy ਵੀ ਚਾਹੀਦੀ ਹੈ।
- Auto Exacto quality signals ਨਾਲ provider selection ਸੁਧਾਰਦਾ ਹੈ। Tools ਤੋਂ ਬਿਨਾਂ requests ਲਈ opt-in route ਵੀ ਹੈ।
- Effective cost ਵਿੱਚ output, cache behavior, retries ਅਤੇ ਸਫਲ task completion ਸ਼ਾਮਲ ਹਨ।
ਲੋੜਾਂ: JSON requests ਦੀ ਜਾਣਕਾਰੀ ਅਤੇ ਆਪਣੀ application ਦੀ OpenRouter configuration ਤੱਕ ਪਹੁੰਚ। Endpoint inspection public API ਵਰਤਦੀ ਹੈ। Model requests ਭੇਜਣ ਲਈ API key ਅਤੇ usage charges ਲੋੜੀਂਦੇ ਹਨ। ਕਿਸੇ dated example ਨੂੰ ਦੁਬਾਰਾ ਵਰਤਣ ਤੋਂ ਪਹਿਲਾਂ endpoint metadata ਫਿਰ ਜਾਂਚੋ।
ਸਮਾਂ ਅਤੇ ਮੁਸ਼ਕਲ: ਪਹਿਲੀ configuration review ਲਈ ਲਗਭਗ 20 ਮਿੰਟ। ਦਰਮਿਆਨਾ ਪੱਧਰ। Providers ਦੀ ਚੰਗੀ ਤੁਲਨਾ ਲਈ representative prompts ਨਾਲ ਹੋਰ testing ਲੋੜੀਂਦੀ ਹੈ।
Model name ਕੀ ਨਹੀਂ ਦੱਸਦਾ
Model identifier ਮੰਗਿਆ ਹੋਇਆ model ਚੁਣਦਾ ਹੈ। Provider inference service ਚਲਾਉਂਦਾ ਹੈ, ਜਿਸ ਵਿੱਚ model implementation, token limits ਅਤੇ tool-call parser ਸ਼ਾਮਲ ਹਨ। Model-level benchmark ਹਰ service ਨੂੰ validate ਨਹੀਂ ਕਰਦਾ ਜੋ ਇਹ weights host ਕਰਦੀ ਹੈ।
| Endpoint property | ਕੀ ਜਾਂਚਣਾ ਹੈ |
|---|---|
| Context length | Prompt, history, tool results ਅਤੇ generation ਲਈ ਥਾਂ |
| Maximum completion length | Requested task ਲਈ output allowance |
| Supported parameters | Tool use, structured output, sampling ਅਤੇ reasoning controls |
| Quantization | Original release ਨਾਲ ਤੁਲਨਾ ਕੀਤਾ reported format |
| Pricing | Input, output, cache reads ਅਤੇ ਵਾਧੂ charges |
| Serving behavior | Completion quality, parsing errors, latency ਅਤੇ retries |
Baseline routing healthy candidates ਵਿੱਚ ਘੱਟ ਕੀਮਤਾਂ ਨੂੰ ਤਰਜੀਹ ਦਿੰਦੀ ਹੈ। OpenRouter inverse-square price weighting document ਕਰਦਾ ਹੈ। ਇਸਦੇ simplified example ਵਿੱਚ $1 candidate ਨੂੰ $3 candidate ਨਾਲੋਂ ਨੌਂ ਗੁਣਾ selection weight ਮਿਲਦਾ ਹੈ। ਇਹ relative weights ਹਨ, ਅਗਲੀ request ਦੀ guarantee ਨਹੀਂ। Explicit ordering, sorting, caching ਅਤੇ quality routing ਵੀ selection ਨੂੰ ਪ੍ਰਭਾਵਿਤ ਕਰਦੇ ਹਨ। Provider routing documentation ਵੇਖੋ।
Price weighting ਤੁਹਾਡੇ workload ਦਾ ਸਭ ਤੋਂ ਸਸਤਾ bill ਸਾਬਤ ਨਹੀਂ ਕਰਦੀ। Documented example input/output mixture ਦੀ universal definition ਨਹੀਂ ਦਿੰਦਾ। Provider ਦੀ selection probability ਸਿਰਫ input price ਤੋਂ ਨਾ ਕੱਢੋ।
Precision ਨੂੰ context ਵਿੱਚ ਪੜ੍ਹੋ
Quantization numerical values ਨੂੰ reduced representation ਵਿੱਚ store ਕਰਦੀ ਹੈ। ਇਸਦਾ ਪ੍ਰਭਾਵ model, method ਅਤੇ inference implementation ਉੱਤੇ ਨਿਰਭਰ ਹੁੰਦਾ ਹੈ। Lower precision testing ਦੀ ਮੰਗ ਕਰਦੀ ਹੈ, ਪਰ label ਇਕੱਲਾ ਇਹ ਨਹੀਂ ਦਿਖਾਉਂਦਾ ਕਿ provider ਨੇ original weights ਬਦਲੇ ਹਨ।
GPT-OSS ਇੱਕ ਸਾਫ਼ ਉਦਾਹਰਨ ਹੈ। OpenAI ਦੀ gpt-oss-120b release documentation ਦੱਸਦੀ ਹੈ ਕਿ mixture-of-experts weights MXFP4 ਵਰਤਦੇ ਹਨ ਅਤੇ evaluations ਨੇ ਉਹੀ quantization ਵਰਤੀ। ਇਨ੍ਹਾਂ weights ਲਈ four-bit label published release ਨਾਲ ਮਿਲਦਾ ਹੈ। ਇਹ provider ਦੀ ਵਾਧੂ downgrade ਦਾ ਸਬੂਤ ਨਹੀਂ।
Upcasting stored values ਨੂੰ wider representation ਵਿੱਚ ਬਦਲਦਾ ਹੈ। ਪਹਿਲਾਂ ਹੀ quantized checkpoint ਨੂੰ BF16 ਵਿੱਚ ਬਦਲਣ ਨਾਲ quantization ਵਿੱਚ ਗੁਆਚੀ ਜਾਣਕਾਰੀ ਵਾਪਸ ਨਹੀਂ ਆਉਂਦੀ। Higher-precision checkpoint ਨੂੰ four bits ਵਿੱਚ ਬਦਲਣਾ ਵੱਖਰਾ ਬਦਲਾਅ ਹੈ, ਜਿਸਦੀ evaluation ਕਰਨੀ ਚਾਹੀਦੀ ਹੈ।
| Observation | Supported conclusion |
|---|---|
| Native MXFP4 checkpoint | Four-bit expert weights release ਦਾ ਹਿੱਸਾ ਹਨ |
| BF16 endpoint label | Wider reported format, better answers ਦਾ ਸਬੂਤ ਨਹੀਂ |
| Unknown precision | Metadata ਨਹੀਂ, hidden degradation ਦਾ ਸਬੂਤ ਨਹੀਂ |
| Matching precision labels | Equivalent serving behavior ਲਈ evidence ਕਾਫ਼ੀ ਨਹੀਂ |
Matching labels quantization differences ਨੂੰ ਵੀ rule out ਨਹੀਂ ਕਰਦੇ। ਉਹ ਇਹ ਵੇਰਵੇ ਛੱਡ ਦਿੰਦੇ ਹਨ ਕਿ ਕਿਹੜੇ tensors quantized ਸਨ, calibration choices ਕੀ ਸਨ ਅਤੇ execution kernels ਕਿਹੜੇ ਸਨ। Bit depth ਨੂੰ quality ranking ਸਮਝਣ ਦੀ ਥਾਂ ਪੂਰੇ endpoint ਦੀ testing ਕਰੋ।
Token budget ਜਾਂਚੋ
curl --fail --silent --show-error \
  'https://openrouter.ai/api/v1/models/openai/gpt-oss-120b/endpoints' \
  | jq '.data.endpoints[] | {
      name,
      provider_name,
      context_length,
      max_completion_tokens,
      supported_parameters,
      quantization,
      pricing
    }'
Endpoints API ਇੱਕ model ਲਈ provider-level metadata ਦਿੰਦੀ ਹੈ। ਇਹ command curl ਅਤੇ jq ਮੰਗਦੀ ਹੈ। Service ਚੁਣਨ ਤੋਂ ਪਹਿਲਾਂ
live gpt-oss-120b endpoint response
inspect ਕਰੋ। Missing ਜਾਂ null fields ਨੂੰ unknown ਮੰਨੋ, unlimited ਨਹੀਂ। Results compare ਕਰਦੇ ਸਮੇਂ dated local snapshot save ਕਰੋ।
5 October 2026 ਦੀ check ਨੇ gpt-oss-120b ਲਈ ਇਹ advertised limits ਵਾਪਸ ਕੀਤੀਆਂ। ਇਹ metadata values ਹਨ, measured completion lengths ਨਹੀਂ। Providers ਸਮੇਂ ਨਾਲ ਇਹਨਾਂ ਨੂੰ ਬਦਲਦੇ ਹਨ।
| Provider | Context tokens | Maximum completion tokens |
|---|---|---|
| DigitalOcean | 128,000 | 4,096 |
| Novita | 131,072 | 32,768 |
| Together | 131,072 | 117,964 |
Context length ਅਤੇ output length ਵੱਖਰੀਆਂ limits ਹਨ। Long-context model ਨੂੰ ਵੀ answer ਲਈ ਥਾਂ ਚਾਹੀਦੀ ਹੈ। Conversation history, system instructions ਅਤੇ tool definitions user document ਨਾਲ ਥਾਂ ਸਾਂਝੀ ਕਰਦੇ ਹਨ।
Reasoning tokens supported reasoning models ਵਿੱਚ generation budget ਵਰਤਦੇ ਹਨ। ਛੋਟਾ allowance incomplete reasoning, ਘੱਟ visible output ਜਾਂ final answer ਤੋਂ ਪਹਿਲਾਂ termination ਕਰ ਸਕਦਾ ਹੈ। Usage ਅਤੇ finish reason inspect ਕਰੋ। ਹਰ short answer ਨੂੰ weaker weights ਨਾਲ ਨਾ ਜੋੜੋ। OpenRouter ਇਸ budget ਨੂੰ reasoning-token documentation ਵਿੱਚ ਸਮਝਾਉਂਦਾ ਹੈ।
Explicit max_tokens router ਨੂੰ requested output length ਦਿੰਦਾ ਹੈ, ਜਿਸਦੀ provider support ਨਾਲ ਤੁਲਨਾ ਕੀਤੀ ਜਾਂਦੀ ਹੈ। Measured task needs ਅਤੇ available context ਤੋਂ value ਚੁਣੋ। ਬਹੁਤ ਵੱਡੀ value eligibility ਘਟਾਉਂਦੀ ਹੈ ਅਤੇ ਲੰਬੇ ਜਾਂ ਚੰਗੇ answer ਦੀ guarantee ਨਹੀਂ ਦਿੰਦੀ।
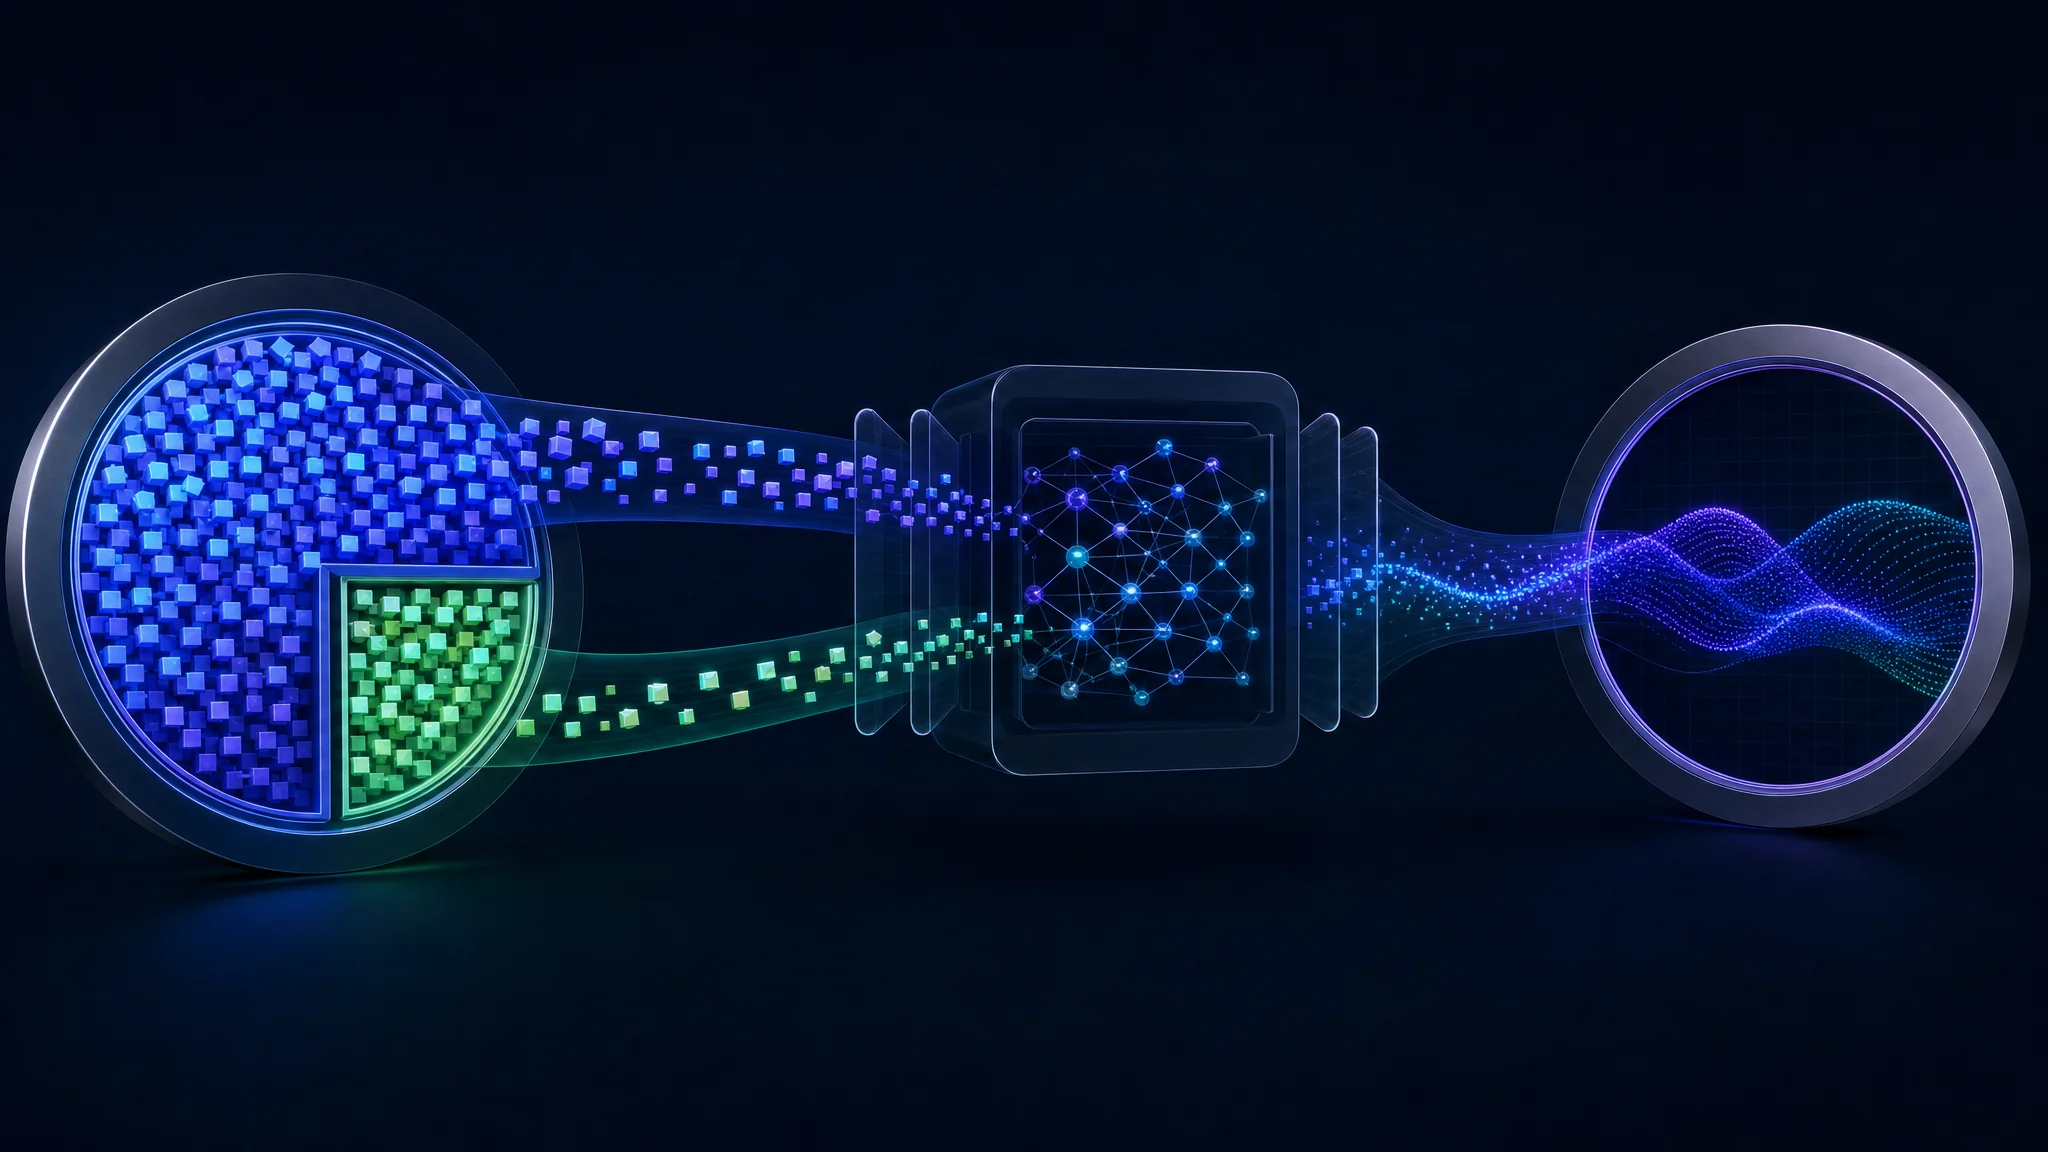
Conceptual token allocation, with reasoning and visible output sharing the completion allowance on supported providers
Parameters ਲਾਜ਼ਮੀ ਕਰੋ
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Explain the failure modes of a retry loop."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
require_parameters ਦੀ default value false ਹੈ। Default routing ਵਿੱਚ unsupported parameters endpoint ਨੂੰ ਹਮੇਸ਼ਾ exclude ਨਹੀਂ ਕਰਦੇ। OpenRouter unknown parameters ignore ਕਰਨ ਵਾਲੇ providers document ਕਰਦਾ ਹੈ। ਇਸ field ਨੂੰ true ਕਰਨ ਨਾਲ declared support ਅਨੁਸਾਰ routing filter ਹੁੰਦੀ ਹੈ।
Support metadata behavior guarantee ਨਹੀਂ ਹੈ। Seed support ਦੱਸਣ ਵਾਲੇ endpoint ਨੂੰ reproducibility testing ਦੀ ਫਿਰ ਵੀ ਲੋੜ ਹੈ। Tool-capable endpoint ਨੂੰ schema validation ਅਤੇ application-level tests ਦੀ ਲੋੜ ਹੈ। Filter known incompatibilities ਨੂੰ candidate set ਵਿੱਚ ਆਉਣ ਤੋਂ ਰੋਕਦਾ ਹੈ।
Providers ਨੂੰ ਸੋਚ ਕੇ pin ਕਰੋ
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Summarize the supplied incident report."}
  ],
  "max_tokens": 8192,
  "provider": {
    "order": ["REPLACE_WITH_VERIFIED_PROVIDER_SLUG"],
    "allow_fallbacks": false,
    "require_parameters": true
  }
}
Placeholder ਨੂੰ ਬਦਲੋ model ਦੀ provider listing ਤੋਂ copy ਕੀਤੇ provider slug ਨਾਲ। ਆਪਣੀ real request ਵਿੱਚ report ਭੇਜੋ। ਇਹ template configuration review ਲਈ ਹੈ। Placeholder ਬਦਲੇ ਬਿਨਾਂ ਇਹ runnable request ਨਹੀਂ।
order preference ਤੈਅ ਕਰਦਾ ਹੈ। ਇਕੱਲਾ ਵਰਤਿਆਂ ਹੋਰ providers ਲਈ fallback enabled ਰਹਿੰਦਾ ਹੈ। allow_fallbacks: false ਨਾਲ routing listed providers ਤੱਕ ਸੀਮਤ ਹੁੰਦੀ ਹੈ। ਜਦੋਂ ਕੋਈ provider request satisfy ਨਾ ਕਰੇ ਜਾਂ available ਨਾ ਰਹੇ, request fail ਹੋਣ ਦੀ ਉਮੀਦ ਰੱਖੋ।
Endpoint variants ਵੱਲ ਧਿਆਨ ਦਿਓ। Base provider slug documented matching rules ਅਨੁਸਾਰ ਕਈ variants ਨਾਲ match ਕਰਦਾ ਹੈ। ਖਾਸ service configuration test ਕਰਦੇ ਸਮੇਂ specific variant slug ਵਰਤੋ। ਹਰ response ਵਿੱਚ reported provider ਫਿਰ ਜਾਂਚੋ।
quantizations named formats ਦੀ allowlist ਹੈ, numerical minimum ਨਹੀਂ। "fp8" ਵਾਲਾ array matching FP8 endpoints ਚੁਣਦਾ ਹੈ। ਇਹ BF16 ਜਾਂ ਵੱਧ bits ਵਾਲੇ ਸਾਰੇ formats ਨੂੰ ਆਪਣੇ ਆਪ ਸ਼ਾਮਲ ਨਹੀਂ ਕਰਦਾ। ਪਹਿਲਾਂ original checkpoint compare ਕਰੋ, ਫਿਰ evaluation support ਕਰੇ ਤਾਂ filter ਲਗਾਓ।
Quality routing ਚਾਲੂ ਰੱਖੋ
{
  "model": "openai/gpt-oss-120b:exacto",
  "messages": [
    {"role": "user", "content": "Compare the two supplied incident reports."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
Auto Exacto throughput, tool-call telemetry ਅਤੇ benchmarks ਵਰਤ ਕੇ ਘੱਟ performance ਵਾਲੇ providers ਨੂੰ ਹੇਠਾਂ ਕਰਦਾ ਹੈ। OpenRouter ਦੀ March 2026 announcement GLM-5 tool-call errors ਵਿੱਚ 88% ਕਮੀ ਦੱਸਦੀ ਹੈ, ਲਗਭਗ 8% ਤੋਂ 1% ਤੱਕ। ਇਹ gpt-oss-120b ਲਈ 5.6% ਤੋਂ 3.5% ਦੀ ਤਬਦੀਲੀ ਵੀ ਦੱਸਦੀ ਹੈ।
ਇਹ provider ਵੱਲੋਂ report ਕੀਤੇ ਨਤੀਜੇ ਹਨ, ਤੁਹਾਡੀ application ਲਈ promise ਨਹੀਂ। Tool-call validity JSON, names ਅਤੇ schemas ਮਾਪਦੀ ਹੈ। Syntactically valid call ਨੂੰ ਵੀ user task ਲਈ ਸਹੀ arguments ਅਤੇ action ਦੀ ਲੋੜ ਹੁੰਦੀ ਹੈ।
Tools ਵਾਲੀਆਂ requests ਨੂੰ model ਦੀ provider coverage ਕਾਫ਼ੀ ਹੋਣ ਉੱਤੇ default ਤੌਰ ਤੇ Auto Exacto ਮਿਲਦਾ ਹੈ। ਹੋਰ requests ਲਈ :exacto quality routing opt in ਕਰਦਾ ਹੈ। Current documentation summarization ਅਤੇ chat ਦੇ ਨਾਲ tool use ਲਈ ਵੀ quality routing support ਕਰਦੀ ਹੈ।
sort: "price", :floor suffix ਅਤੇ account-level default price sort Auto Exacto opt out ਕਰਦੇ ਹਨ। Application settings ਅਤੇ account preferences ਇਕੱਠੇ check ਕਰੋ। Routing controls ਜੋੜਨ ਤੋਂ ਪਹਿਲਾਂ
Auto Exacto documentation
ਪੜ੍ਹੋ।
Workload cost ਕੱਢੋ
Input price ਇਕੱਲੀ ਅਧੂਰੀ comparison ਹੈ। ਹੇਠਾਂ dollars per million tokens ਵਿੱਚ illustrative rates ਹਨ। ਇਹ arithmetic ਦਿਖਾਉਂਦੀਆਂ ਹਨ, current provider quotes ਨਹੀਂ।
| Illustrative endpoint | Input price | Output price |
|---|---|---|
| A | $0.03 | $16.00 |
| B | $0.42 | $1.32 |
Workload: 6 million input tokens + 1 million output tokens

A = 6 × $0.03 + 1 × $16.00 = $16.18
B = 6 × $0.42 + 1 × $1.32  =  $3.84

Per million combined input and output tokens:
A = $16.18 / 7 = $2.31
B =  $3.84 / 7 = $0.55
ਇਸ mixture ਲਈ Endpoint A ਲਗਭਗ 4.2 ਗੁਣਾ ਮਹਿੰਗਾ ਹੈ, ਭਾਵੇਂ input price ਘੱਟ ਹੈ। A ਦਾ 533-to-1 output/input ratio ਦੋ rates ਵਿਚਕਾਰ ratio ਹੈ, user ਦੇ total cost ਦਾ multiplier ਨਹੀਂ। ਵੱਖਰੀ input/output proportion comparison ਬਦਲ ਦਿੰਦੀ ਹੈ।
API pricing units comparison tables ਤੋਂ ਵੱਖਰੀਆਂ ਹਨ। Endpoint API token prices per token ਦਿੰਦੀ ਹੈ। ਉੱਪਰਲੀਆਂ rates ਨਾਲ compare ਕਰਨ ਤੋਂ ਪਹਿਲਾਂ ਇੱਕ million ਨਾਲ ਗੁਣਾ ਕਰੋ।
Prompt caching ਇੱਕ ਹੋਰ variable ਲਿਆਉਂਦੀ ਹੈ। Cached reads, cache writes ਅਤੇ uncached input ਨੂੰ provider billing rules ਅਨੁਸਾਰ ਵੱਖਰਾ account ਕਰੋ। Repeated text cache hit ਦੀ guarantee ਨਹੀਂ। Prompt caching documentation ਵਿੱਚ reported cached-token counts ਅਤੇ costs ਵੇਖੋ।
Routing cache continuity ਨੂੰ ਪ੍ਰਭਾਵਿਤ ਕਰਦੀ ਹੈ। OpenRouter caching ਲਈ sticky routing document ਕਰਦਾ ਹੈ, ਜਦਕਿ manual provider order ਨੂੰ priority ਮਿਲਦੀ ਹੈ। Auto Exacto providers ਨੂੰ reorder ਕਰਦਾ ਹੈ ਅਤੇ ਕਈ ਵਾਰ warm cache ਤੋੜਦਾ ਹੈ। Policy ਬਦਲਣ ਤੋਂ ਪਹਿਲਾਂ observed cache savings ਨੂੰ quality ਅਤੇ retry costs ਨਾਲ compare ਕਰੋ।
Cost per accepted result application ਦੀ useful metric ਹੈ। Total spend, retries ਅਤੇ failed attempts ਸਮੇਤ, acceptance criteria ਪੂਰੇ ਕਰਨ ਵਾਲੇ results ਨਾਲ divide ਕਰੋ। Applicable non-token charges ਵੱਖਰੇ ਸ਼ਾਮਲ ਕਰੋ। Low token rate repeatedly unsuccessful tasks ਦੀ ਭਰਪਾਈ ਨਹੀਂ ਕਰਦੀ।
Inconsistent answer ਦੀ ਜਾਂਚ ਕਰੋ
| Symptom | First check |
|---|---|
| Short ਜਾਂ unfinished response | Finish reason, output allowance, reasoning usage |
| Document details missing | Submitted content, endpoint context limit, client truncation |
| Malformed tool call | Advertised support, tool schema, parsing behavior |
| Different sampling behavior | Requested parameters ਅਤੇ declared support |
| Unexpected expense | Output volume, cache reads, retries, provider changes |
| No eligible provider | Conflicting limits, allowlists ਅਤੇ fallback restrictions |
Response ਨਾਲ ਮਿਲਿਆ generation ID ਸੰਭਾਲੋ। OpenRouter ਦੀ generation metadata API provider identity, usage, cost ਅਤੇ finish information ਦਿੰਦੀ ਹੈ। Session ID related work group ਕਰਦੀ ਹੈ, ਪਰ single request lookup ਲਈ generation ID ਦੀ ਥਾਂ ਨਹੀਂ ਲੈਂਦੀ।
Generation ID ਦੇ ਨਾਲ request save ਕਰੋ। Model, provider preferences, requested parameters, timestamp ਅਤੇ response usage ਰੱਖੋ। Routing, prices ਜਾਂ endpoint metadata ਬਦਲਣ ਉੱਤੇ ਬਾਅਦ ਦੀ quality ਜਾਂ cost comparison reproducible ਰਹੇਗੀ।
Matching conditions ਹੇਠ endpoints compare ਕਰੋ। ਇੱਕੋ prompt, tools, reasoning settings ਅਤੇ token budget ਵਰਤੋ। ਕਈ representative tasks ਉੱਤੇ repeat ਕਰੋ। Incomplete responses, invalid tool calls ਅਤੇ wrong answers ਨੂੰ ਇੱਕ unexplained quality score ਵਿੱਚ ਨਾ ਮਿਲਾਓ।
Benchmark uncertainty ਮਹੱਤਵ ਰੱਖਦੀ ਹੈ। Epoch AI ਦੀ benchmarking analysis implementations, sampling ਅਤੇ agent scaffolds ਤੋਂ variation ਦੱਸਦੀ ਹੈ। ਇੱਕ disappointing answer persistent provider defect ਜਾਂ ਉਸਦੀ cause ਸਾਬਤ ਨਹੀਂ ਕਰਦਾ।
Endpoint routing walkthrough
ਹੋਰ ਵੇਖੋ: OpenRouter endpoint quality and routing discussion । Specific prices, limits ਜਾਂ provider comparisons ਲਾਗੂ ਕਰਨ ਤੋਂ ਪਹਿਲਾਂ endpoint listings ਫਿਰ check ਕਰੋ।
ਅਗਲੇ ਕਦਮ
- ਇੱਕ model ਦੇ endpoints inspect ਕਰੋ ਅਤੇ ਆਪਣੇ workload ਲਈ relevant limits record ਕਰੋ।
- Routing policy ਚੁਣੋ ਜਿਸ ਵਿੱਚ explicit parameter requirements ਅਤੇ fallback behavior ਹੋਵੇ।
- Representative tasks test ਕਰੋ candidate endpoints ਅਤੇ quality routing ਦੇ ਖ਼ਿਲਾਫ਼।
- Accepted-result cost record ਕਰੋ latency, cache usage ਅਤੇ failure categories ਦੇ ਨਾਲ।
- Changes ਤੋਂ ਬਾਅਦ ਫਿਰ check ਕਰੋ model versions, serving behavior ਜਾਂ provider prices ਵਿੱਚ।
ਵਿਆਪਕ AI fundamentals ਲਈ Basic AI Concepts ਪੜ੍ਹੋ। Agent permissions ਅਤੇ validation controls ਲਈ Securing AI Systems ਪੜ੍ਹੋ।
Related Posts